What does llms.txt actually do?
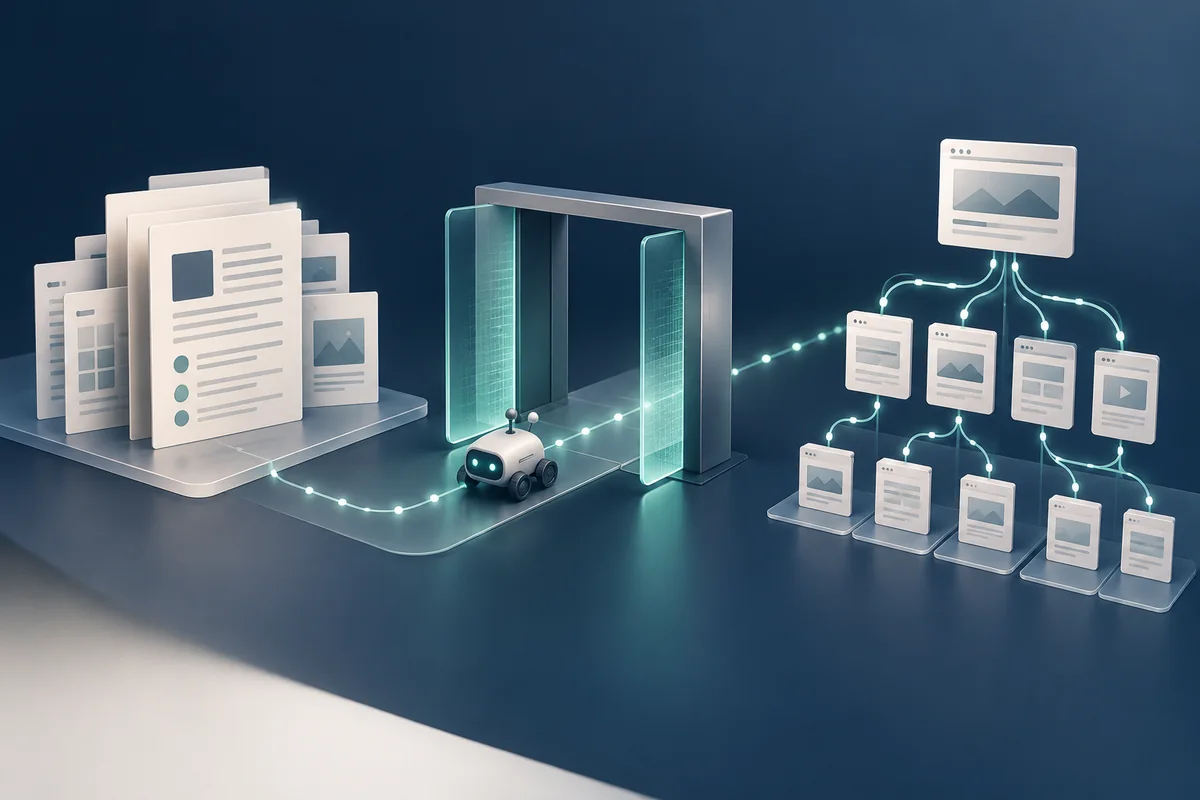
The llms.txt proposal describes a Markdown file, usually at a site's root but also possible within a section, that presents a concise map of useful pages for AI agents. It can include a title, description and links to deeper material. The idea is to make a site easier to navigate when an agent needs a small, relevant set of pages rather than a full crawl. It remains a proposal and an optional publishing convention, so do not describe it as a standard that all major search systems use.
This site already serves an llms.txt file built from its content registry. That can help a reader or agent find important guides, but its presence does not prove an AI product fetched it or used it in an answer. Keep the list accurate when pages change. A file that points to old prices or removed services can confuse a reader even if no search engine uses it.
Why an XML sitemap is different
An XML sitemap lists URLs for search engines to discover and can carry update information. llms.txt is a human-readable proposal for selecting and describing useful material. Neither file grants crawler access by itself. If a firewall blocks the page, listing it in either file will not make its content available. A B2B site should maintain its sitemap because it supports established discovery workflows; llms.txt is an optional extra with a separate maintenance cost.
How does robots.txt control crawler access?
robots.txt gives compliant crawlers instructions about which URL paths they may fetch. It is not access control for private information; sensitive content needs authentication or another real restriction. Different AI providers document different user agents and purposes, so a broad “AI bots” rule can have effects the site owner did not intend. Check the current provider documentation before editing a policy copied from another website.
OpenAI's crawler guide names OAI-SearchBot for search features, GPTBot for potential model training and ChatGPT-User for some user-triggered requests. It says the first two settings are independent. A company may choose to allow search discovery while restricting training, but that is a policy choice for the site owner. Test the deployed robots.txt and the CDN response after any change. A line in source control is not proof that the edge network serves the same policy.
What about Google AI Overviews?
Google's AI features guidance says a page must meet normal Search requirements and be eligible for a snippet to appear as a supporting link. It explicitly says no new AI text file or special AI markup is required. Google's guidance also recommends allowing crawl access, making important pages findable through internal links and keeping key content in text. Creating llms.txt cannot replace those conditions.
For the buyer and measurement consequences of summary answers, read the zero-click B2B search guide.
What should a B2B team check first?
Audit the actual path from discovery to readable content. Start with your service, pricing, product and proof pages. Make sure each page returns a usable response, has a clear canonical URL, is linked from the site and contains the main facts in HTML text. Then examine robots.txt, noindex directives, CDN bot settings and server logs. Only after these basics are sound should the team spend time on an optional agent-oriented index.
| Asset or control | Main purpose | Does it guarantee a citation? |
|---|---|---|
| Service page | Explain scope and buyer fit | No |
| Internal links | Help people and crawlers find pages | No |
| XML sitemap | Advertise canonical URLs for discovery | No |
| robots.txt | State crawl permissions to compliant bots | No |
| llms.txt | Offer a concise page map to agents | No |
| CDN rule | Permit or deny actual requests at the edge | No |
The matrix helps avoid a common category error: treating a page map as a crawler instruction or treating crawler permission as a placement promise. A page can be allowed and still not be chosen for a particular answer. A page can be listed in llms.txt and still be stale, blocked or irrelevant to the buyer's question.
How should you build and maintain llms.txt if you use it?
Select a small set of public, canonical pages that explain what the business does, who it serves and where buyers can verify the offer. Add concise descriptions that match the live page. Avoid private documents, gated assets, duplicate tracking URLs and promotional claims you cannot substantiate. Tie the file to the site's content registry if possible so retired pages do not linger. Review it when pricing, product features or key guides change.
Test it as an ordinary public URL: it should return a successful response, a sensible content type and links that work. Keep a record of what changed and when. Do not claim that a new file caused an AI citation unless you can show a credible measurement design. The technical SEO service page covers the underlying access and index checks, and our ChatGPT citation guide explains how to test answer visibility without promising a result.
How do you audit the crawler policy in practice?
Fetch the live robots.txt from outside the development environment and compare it with the source file or route. Read the rules for the specific user agent you care about, then check whether a CDN or security service adds a challenge. Inspect a sample of server logs to see the status code actually returned to the crawler. Test a representative service page and a page in a deeper directory. A working root page does not prove that every important path is accessible.
Record the decision owner and reason for each rule. Search discovery, model training and user-triggered browsing are different use cases, and a single blanket block can obscure that choice. OpenAI documents separate user agents for those purposes; other providers have their own names and policies. Revisit the list after a provider changes its documentation or the site changes hosting. The correct setting depends on the organisation's publishing and data policy, so keep it explicit rather than copying a competitor's robots.txt.
What would a useful llms.txt contain here?
For a B2B service business, begin with a short description of the company and links to current service, pricing, method, case-study and contact pages. Add a small number of evergreen guides that clarify terms buyers ask about. Avoid a raw export of every blog URL, because a long undifferentiated list gives an agent little guidance about which page matters. Check that each link resolves to its canonical URL and that the description agrees with the visible page. If the file is generated automatically, review the output after any route or pricing change.
The file should not contain private sales material or confidential client evidence. Public pages should explain what can be verified and what must be discussed under a client agreement. An llms.txt file can point to that public explanation, but it cannot make a private claim safe to publish. Treat the file as another editorial surface with an owner, review schedule and broken-link check. Its value is maintainable clarity, not a ranking promise.